
Marketing Mix Modeling: allocating the advertising budget
Darko Macoritto
· 5 min
Robyn (Meta) rests on past data alone; LightweightMMM (Google) adds prior knowledge. To choose between them, a preliminary study fitted to the business model validates the results more rigorously.
Swipe left to read
Keep reading
Robyn (Meta) rests on past data alone; LightweightMMM (Google) adds prior knowledge. To choose between them, a preliminary study fitted to the business model validates the results more rigorously.
Introduction
Marketing mix modeling (MMM) is a set of statistical methods for assessing the impact of different marketing activity on a company’s sales and revenue. That decision-making approach therefore lets the marketing budget be allocated optimally across channels and promotional activity. Presented at Perspective 4, two MMM exercises run with La Redoute Suisse led to part of the budget being moved from Fashion to Home, judged more profitable.
MMM rests on the analysis of time series of sales data and marketing costs. Whether through simple regressions or advanced machine learning techniques, MMM ultimately models the return on investment (ROI) of each piece of marketing, and makes the impact of future scenarios predictable.
This article introduces two well-known methods used for this kind of analysis, why they are useful and how they differ.
The ways of going about it
For a company wanting to carry out an MMM, there are in fact many ways to proceed. You can, for instance:
- Call on specialist companies with proprietary models, often SaaS
- Launch your own method
- Use existing open-source code and fit it to your business
Proprietary models often have the advantage of being simpler to use. Their method nonetheless stays obscure, in the sense that the owners may be reluctant to reveal the mechanics of their models, so as to keep their craft exclusive. What is more, in SaaS, the particularities of your company will be hard to bring in, unless the owning company makes bespoke changes — which limits the advantages of a SaaS solution.
As for coding your own model, that is an enormous challenge. You need deep knowledge of machine learning and econometrics. You also have to devote a great deal of time to testing, to coding the program and so on. We do not recommend this route unless the SaaS and open-source models cannot be applied to your company.
Finally, there are the open-source models, the most popular being Robyn and LightweightMMM. One is developed by Meta, the other by Google. Each has its own method. Although their source code is available online, no assistance is provided for setting them up, which calls for advanced expertise in programming and data science to calibrate the model.
Robyn vs LightweightMMM
Although Robyn and LightweightMMM have technical differences, their fundamental aim is the same: feed the model with marketing costs and sales, so as to identify the effect of each marketing channel on sales.
Among the models’ similarities, both take two very important advertising phenomena into account:
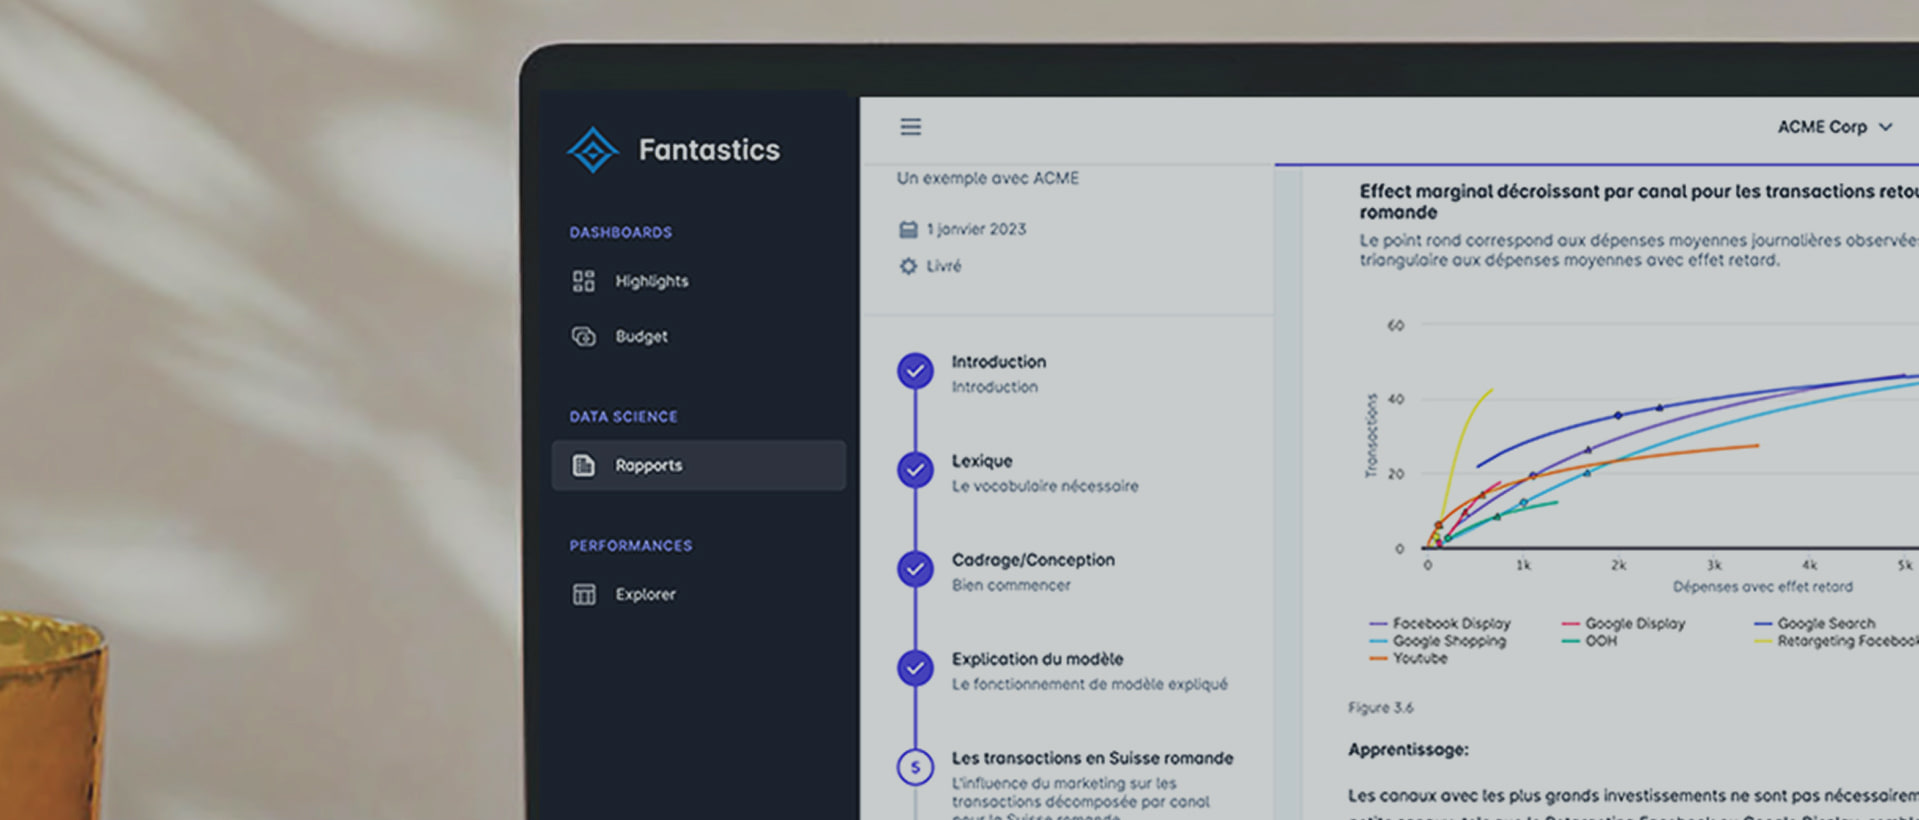
- Diminishing marginal effect: simply explained through the example of advertising. A business owner decides to invest in advertising to grow sales. At first, every CHF invested in advertising raises sales considerably. But as they keep investing in the same media lever, the rise in sales for each further CHF invested becomes smaller and smaller. That is the diminishing marginal effect.
- Lag effect (adstock): the lag effect is a concept used to account for advertising’s carry-over. Adstock refers to the amount of impact an advert has on consumer behaviour after the advertising stops. To explain it simply, take a company launching an advertising campaign for a new product. Even after the campaign ends, consumers may go on remembering the product and buying it, through advertising’s residual effect. That is the lag effect.
The difference between the models lies in how those phenomena are measured. Robyn uses a frequentist method, while LightweightMMM uses Bayesian techniques. Without going into the technical detail, frequentist methods estimate the parameters sought by observing past data alone. Bayesian models call for prior knowledge of the effects. To estimate a channel’s ROI — Google Search, say — the Bayesian model will ask us for a range of values to supply, which will guide its analysis. The frequentist model will ask for nothing and will calculate that value from the past.
Which is better?
As always with this kind of question, the answer is “it depends”. Here nonetheless are a few elements for comparison:
- Robyn is a package officially supported by Meta, while LightweightMMM is a package developed by Google employees but without the company’s official support. That distinction affects the effort invested in maintaining and developing the package, since Meta’s employees have improving it continuously as part of their job. For LightweightMMM, by contrast, development is done voluntarily. It shows in the end result, in the sense that Robyn is better finished and better documented.
- Bayesian methods let prior knowledge be brought into the model. That is relatively useful when certain channels have been assessed individually in the past — through a Conversion Lift or a Geographic Lift, for instance — and we have an idea of their ROI. Bringing that knowledge in gives a model coherent with the known context. That is LightweightMMM’s strength.
Although Robyn was not initially designed to take prior knowledge, the package’s creators have now provided ways of guiding the model with indications given before the modelling. That replicates LightweightMMM’s concept, after a fashion. - Since Robyn leans more heavily on past data, it generally needs more data to be precise.
The emergence of LightweightMMM, the more recent package, recently pushed us to revisit our approach, which had rested on Robyn. Bayesian techniques are an interesting approach, because they give the analyst more control. If LightweightMMM receives stronger attention from the marketing analyst community and develops well, it could become more popular than Robyn.
Update, September 2026: Google has since announced that its own open-source model, Meridian, will be built into GA360, along with an interface, Meridian Studio; see our reading of Google Marketing Live 2026.
Our final recommendation today is to carry out a preliminary study which, depending on your business model, will settle the choice between the two models and bring out the potential differences and common ground between the approaches. That makes for a more rigorous validation of the results. At bright, we carry out that preliminary study notably so as to fit our fantastics framework to the project — handling the data, presenting the results, the intermediate calculations to carry out — to choose the right model and to set the scope of the modelling to come.
The series : MMM explained in three chapters
- Marketing Mix Modeling10 publications
The key skills bright can bring to you